Flow Matching for Generative Modeling
About the paper
- Published at ICLR 2023 (splotlight, top 5%)
- Affiliations: Meta AI, Weizmann Institute of Science
- Link to the paper: https://openreview.net/pdf?id=PqvMRDCJT9t
Introduction
Continuous Normalizing Flows (CNF) is a class of generative models that can be trained by maximum likelihood. The main idea is to transform a simple distribution (e.g., Gaussian) to a complex distribution (e.g., ImageNet dataset) by a series of invertible transformations. The main challenge is to design a transformation that is invertible and can be computed efficiently.
The flow \(\phi_t(x)\) presents a time-dependent diffeomorphic map that transforms the input \(x\) to the output \(y\) at time \(t\). The flow is defined as follows:
\[\frac{d}{dt} \phi_t(x) = v_t(\phi_t(x))\]where \(v_t\) is a time-dependent vector field. \(\phi_0(x) = x\) means that the flow at time \(t=0\) is the identity map.
Given \(p_0\) is the simple distribution (e.g., Gaussian), the flow \(\phi_t\) transforms \(p_0\) to \(p_t\) as follows:
\[p_t = [ \phi_t ] * p_0\]where \([ \phi_t ] * p_0\) is the push-forward measure of \(p_0\) under the map \(\phi_t\). The push-forward measure is defined as follows:
\[[ \phi_t ] * p_0(A) = p_0(\phi_t^{-1}(A))\]where \(A\) is a subset of the output space. The push-forward measure can be interpreted as the probability of the output \(y\) falls into the subset \(A\).
\[p_t(x) = p_0(\phi_t^{-1}(x)) \left| \det \frac{d \phi_t^{-1}(x)}{dx} \right|\]The function \(v_t\) can be intepreted as the velocity of the flow at time \(t\), i.e., how fast the flow moves at time \(t\). In comparison with diffusion process, the velocity \(v_t\) is similar as the denoising function that is used to denoise the image \(x\) at time \(t\), where \(\phi_t(x)\) is the distribution of the denoised images at time \(t\).
Flow matching objective: Given a target probability density path \(p_t(x)\) and a corresponding vector field \(u_t(x)\) which generates \(p_t(x)\), the flow matching objective is to find a flow \(\phi_t(x)\) and a corresponding vector field \(v_t(x)\) that generates \(p_t(x)\).
\[\mathcal{L}_{FM} (\theta) = \mathbb{E}_{t, p_t(x)} \| v_t(x) - u_t(x) \|\]It is a bit confusing in notation here, so \(u_t(x)\) can be understand as the target vector field that generates the target probability density path \(p_t(x)\), while \(v_t(x)\) is the vector field to be learned to approximate \(u_t(x)\).
It can be seen that the Flow Matching objective is a simple and attractive objective but intractable to use because we don’t know the target vector field \(u_t(x)\). The main contribution of the paper is to propose the way to simplify the above objective function. And their approach is quite similar as in DDPM where the solution relies on conditioning to a previous point in the sequence.
The marginal probability path
\[p_t(x) = \int p_t(x \mid x_1) q(x_1) dx_1\]where $x_1$ is a particular data sample, and \(p_t(x \mid x_1)\) is the conditional probability path such that \(p_t(x \mid x_1) = p_t(x)\) at time \(t=0\). The important point is that they design the \(p_1(x \mid x_1)\) at time \(t=1\) to be a normal distribution around \(x_1\) with a small variance, i.e., \(p_1 (x \mid x_1) = \mathcal{N}(x_1, \sigma^2 I)\). In the above equation, \(q(x_1)\) is the prior distribution of \(x_1\).
Where in particular at time \(t=1\), the marginal probability path \(p_1\) will approximate the data distribution \(q\),
\[p_1(x) = \int p_1(x \mid x_1) q(x_1) dx_1 \approx q(x)\]And the vector field \(u_t(x)\) can be defined as follows:
\[u_t(x) = \int u_t(x \mid x_1) \frac{p_t (x \mid x_1) q(x_1)}{p_t(x)} dx_1\]Theorem 1: Given vector fields \(u_t(x \mid x_t)\) that generate conditional probability paths \(p_t(x \mid x_t)\) for any distribution \(q(x_1)\), the marginal vector field \(u_t(x)\) in the above equation generates the marginal probability path \(p_t(x)\).
So it means that if we can learn \(u_t (x \mid x_t)\) we can obtain \(u_t(x)\) and then we can use \(u_t(x)\) to generate \(p_t(x)\).
Now we can rewrite the Flow Matching objective to Conditional Flow Matching objective as follows:
\[\mathcal{L}_{CFM} (\theta) = \mathbb{E}_{t, q(x_1), p_t(x \mid x_1)} \| v_t(x) - u_t(x \mid x_1) \|\]where \(v_t(x)\) is the vector field to be learned to approximate \(u_t(x \mid x_1)\). Now the question is how can we obtain \(u_t(x \mid x_1)\)?
In the work, they consider conditional probability paths
\[p_t(x \mid x_1) = \mathcal{N} (x \mid \mu_t (x_1), \sigma_t (x_1)^2 I)\]where \(\mu_t (x_1)\) and \(\sigma_t (x_1)\) are the mean and variance of the conditional probability path \(p_t(x \mid x_1)\), and they are time-dependent. Later, they will show that we can choose \(\mu_t (x_1)\) and \(\sigma_t (x_1)\) very flexiblely, as long as they can satisfy some conditions, for example, \(\mu_0 (x_1) = 0\) and \(\sigma_0 (x_1) = 1\), and \(\mu_1 (x_1) = x_1\) and \(\sigma_1 (x_1) = \sigma_{min}\), which is set sufficiently small so that \(p_1 (x \mid x_1)\) is a concentrated distribution around \(x_1\).
The canonical transformation for Gaussian distributions is defined as follows:
\[\psi_t (x) = \mu_t (x_1) + \sigma_t (x_1) \odot x\]where \(\psi_t (x)\) is the canonical transformation of \(p_t(x \mid x_1)\), and \(\odot\) is the element-wise multiplication.
From the Gaussian transformation to a velocity
Let us make the notation precise before differentiating. We use \(x_0\sim\mathcal{N}(0,I)\) for noise and \(x_1\sim q\) for a data sample, drawn independently. Thus \(q\) is the data distribution; \(p_0\) is the noise prior. The conditioning variable in the formulas above is the endpoint \(x_1\), including in Theorem 1, rather than the current point \(x_t\). Also, \(\sigma_t\) denotes a standard deviation, so the covariance is \(\sigma_t^2 I\). A flow map transforms individual points; the collection of transformed points has density \(p_t\).
For a fixed \(x_1\), the Gaussian transformation gives us a point anywhere along the conditional path:
We can differentiate this expression while holding the sampled pair fixed:
The dot denotes a time derivative. This already supplies a training target, but a vector field takes the current location \(x\) as input. Since \(\sigma_t>0\), we can recover the starting noise through
Substituting gives the conditional velocity:
The first term moves the Gaussian’s center; the second expands or contracts points around that center. This is the velocity of the specified affine flow. Other flows can produce the same density path, so this construction does not claim that a Gaussian distribution has only one possible velocity field. This is Theorem 3 of the paper.
Why conditional training learns the marginal flow
The paper’s equivalence result uses squared Euclidean distance. The two objectives written earlier therefore need their squared-L2 form for the following argument:
Here \(t\sim\mathcal{U}[0,1]\). We can sample the second objective even though the first contains the unknown marginal velocity. To understand why this works, consider all endpoints that could have produced the same location at the same time. Their conditional velocities need not agree. The marginal velocity averages them using the posterior probability of each endpoint:
This is exactly the weighted integral introduced above. The weights depend on both the data distribution and how likely each endpoint’s conditional path is to visit \(x\).
Write the regression error as
After squaring and taking expectations, the cross term vanishes: conditioned on \(t,x\), the second bracket has mean zero. Consequently,
and therefore
This assumes fixed target paths independent of \(\theta\) and sufficient regularity to exchange differentiation and expectation. The paper states the result for positive marginal densities. The gradients agree in expectation; individual minibatch gradients can differ. Moreover, a perfect marginal model can still have positive CFM loss because different conditional targets disagree at the same input. Theorem 2 and Appendix A establish the equivalence.
This also resolves an apparent problem: the model does not need to know the future data sample during generation. We train \(v_t(x;\theta)\) on conditional targets, but it receives only \(t,x\) and learns their conditional mean. Conditioning on a class label or a low-resolution image would be a separate, optional input.
Optimal Transport conditional paths
The general Gaussian formula allows many schedules. The paper’s particularly simple choice is
Let \(a=1-\sigma_{\min}\). The sampled path and its velocity become
For each fixed pair, the velocity is constant: the point travels along a straight line. Substitution into the Gaussian velocity formula gives
At a fixed location this field can vary with time. Its value is constant along a particular conditional trajectory, as the expression \(x_1-ax_0\) shows.
The endpoints deserve attention:
Thus the final conditional distribution is \(\mathcal{N}(x_1,\sigma_{\min}^2I)\), and the marginal endpoint is the data distribution convolved with that small Gaussian:
It approximates the data distribution; it is not exactly \(q\) when \(\sigma_{\min}>0\). In the limit \(\sigma_{\min}\to0\) we obtain the familiar interpolation \(x_t=(1-t)x_0+tx_1\) and target \(x_1-x_0\). Setting it exactly to zero makes the conditional endpoint a point mass and the location-based formula singular at \(t=1\). The sampled-pair velocity remains well defined, but the positive-density argument needs an endpoint limit.
Why call this Optimal Transport? For a fixed endpoint \(x_1\), the map \(x_0\mapsto x_1+\sigma_{\min}x_0\) is the quadratic-cost optimal transport map between the two conditional Gaussians. Interpolating between the identity and that map yields precisely the path above. However, independent noise–data pairing does not solve a global optimal coupling between \(p_0\) and \(q\). The paper explicitly distinguishes these claims in Section 4.1.
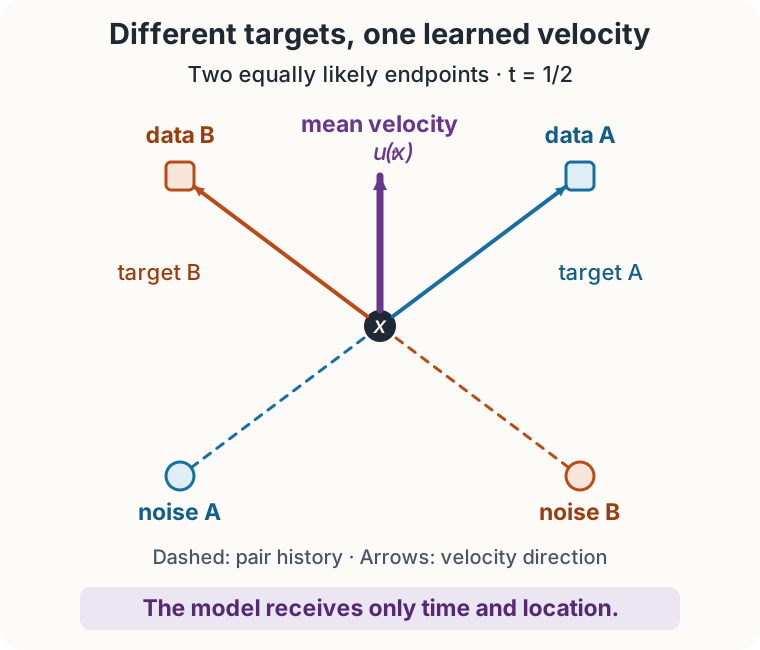
The figure shows why the learned marginal trajectories need not be straight. Their direction changes as the posterior weights change along the path. The crossing lines belong to different conditional fields; they are not two trajectories crossing under one smooth marginal ODE at the same time. Conditional straightness therefore does not guarantee exact generation in one Euler step.
How does this compare with diffusion paths?
Flow Matching is a training objective; the probability path is a separate choice. A diffusion path can also supply the Gaussian means and standard deviations used in the derivation above.
For example, let \(s\) denote forward diffusion time and define a variance-preserving schedule
Reversing time with \(s=1-t\) gives the noise-to-data conditional path
Using \(\mu_t=\alpha_{1-t}x_1\) and \(\sigma_t=\sqrt{1-\alpha_{1-t}^2}\) in our general formula yields its conditional velocity. Unlike the linear OT schedule, its two coefficients generally change nonlinearly, so conditional trajectories can curve and their speeds vary. With a finite diffusion schedule, \(\alpha_1\) is small but usually nonzero: the initial distribution only approximates pure Gaussian noise. The OT construction above starts at the specified Gaussian exactly.
The conditional score for a Gaussian path is
so its velocity can also be written as
This connects score prediction and velocity prediction without making their unweighted training losses identical: changing the prediction target also changes the effective time weighting. For the VP and VE paths considered in the paper, the construction agrees with the corresponding probability-flow ODE. That ODE shares time marginals with the diffusion process; its deterministic trajectories are not stochastic diffusion sample paths. See Appendix D and Song et al..
Training and sampling
With the OT schedule, one training example requires a data sample, fresh Gaussian noise, and a uniformly sampled time. Both the location and velocity target are available directly:
The following PyTorch-style pseudocode implements this loss. The model accepts one time value per batch item and predicts a tensor with the same shape as the input. The standard deviation below is an illustrative hyperparameter.
import torch

def train_step(model, optimizer, x1, sigma_min=1e-3):
    # x1: a batch of preprocessed data, shape [batch, ...]
    model.train()
    batch = x1.shape[0]
    x0 = torch.randn_like(x1)
    t = torch.rand(batch, device=x1.device, dtype=x1.dtype)
    time_shape = (batch,) + (1,) * (x1.ndim - 1)
    t_broadcast = t.reshape(time_shape)
    a = 1.0 - sigma_min

    xt = (1.0 - a * t_broadcast) * x0 + t_broadcast * x1
    target = x1 - a * x0
    prediction = model(t, xt)
    loss = (prediction - target).square().flatten(1).sum(1).mean()

    optimizer.zero_grad()
    loss.backward()
    optimizer.step()
    return loss.detach()
There is no ODE solve, trajectory rollout, or divergence estimate inside this training step. This is the meaning of simulation-free training. It does not remove the integration needed to generate a sample.
After training, draw \(z_0\sim\mathcal{N}(0,I)\) and integrate
Here is a fixed-step midpoint solver. Each step evaluates the network twice: once to estimate the midpoint, then again to move using the velocity there.
@torch.no_grad()
def sample(model, shape, device, steps=100, dtype=torch.float32):
    assert steps > 0
    model.eval()
    z = torch.randn(shape, device=device, dtype=dtype)
    batch = shape[0]
    dt = 1.0 / steps

    for k in range(steps):
        t = torch.full((batch,), k * dt, device=device, dtype=dtype)
        first_velocity = model(t, z)
        midpoint = z + 0.5 * dt * first_velocity
        midpoint_velocity = model(t + 0.5 * dt, midpoint)
        z = z + dt * midpoint_velocity

    return z  # Apply the inverse of the training data preprocessing.
This sampler uses \(2\times\texttt{steps}\) network evaluations. The step count is a numerical-accuracy choice, not a consequence of the number of training times. Adaptive solvers instead adjust their steps using error tolerances. Neither solver has access to a target data endpoint.
What do the experiments show?
The paper separates the effect of the loss from the effect of the path. Its ImageNet-64 ablation uses the same U-Net architecture across the methods below. These are unconditional generation results from Table 1; lower values are better.
| Training method | NLL (bits/dimension) | FID | Mean NFE |
|---|---|---|---|
| DDPM baseline | 3.32 | 17.36 | 264 |
| Flow Matching with diffusion path | 3.33 | 16.88 | 187 |
| Flow Matching with OT path | 3.31 | 14.45 | 138 |
NFE is the number of vector-field evaluations made by the adaptive ODE solver, averaged over 50,000 samples. These results use dopri5 with absolute and relative tolerances of \(10^{-5}\), including for the diffusion baselines. Thus the DDPM row should not be read as an ancestral sampler with 264 prescribed diffusion steps.
In this comparison, changing to velocity regression reduces sampling work, and changing the path to conditional OT improves the reported metrics further. The separate ImageNet-32 fixed-step experiment also reports lower numerical error at a given evaluation budget. These are empirical results for the architectures, training budgets, and solvers studied, rather than a guarantee that OT paths outperform every diffusion model.
Several limitations remain visible in the construction. The target path is a design choice; finite network capacity may fit some parts better than others. The endpoint variance introduces smoothing. Approximate velocity prediction and numerical integration both affect samples, and fewer solver steps can reduce quality. Finally, the conditional OT argument does not establish globally optimal or straight marginal transport. What the method provides is a tractable regression objective for learning the vector field of a chosen probability path.
References
- Lipman, Y., Chen, R. T. Q., Ben-Hamu, H., Nickel, M., and Le, M. Flow Matching for Generative Modeling. ICLR 2023. Theorems 1–3, Section 4, Table 1, and Appendices A, D, E provide the derivations and experimental details used here.
- Song, Y. et al. Score-Based Generative Modeling through Stochastic Differential Equations. ICLR 2021. The probability-flow ODE connection underlying the diffusion comparison.
- Chen, R. T. Q., Rubanova, Y., Bettencourt, J., and Duvenaud, D. Neural Ordinary Differential Equations. NeurIPS 2018. Background on continuous normalizing flows and numerical ODE evaluation.
Enjoy Reading This Article?
Here are some more articles you might like to read next: